

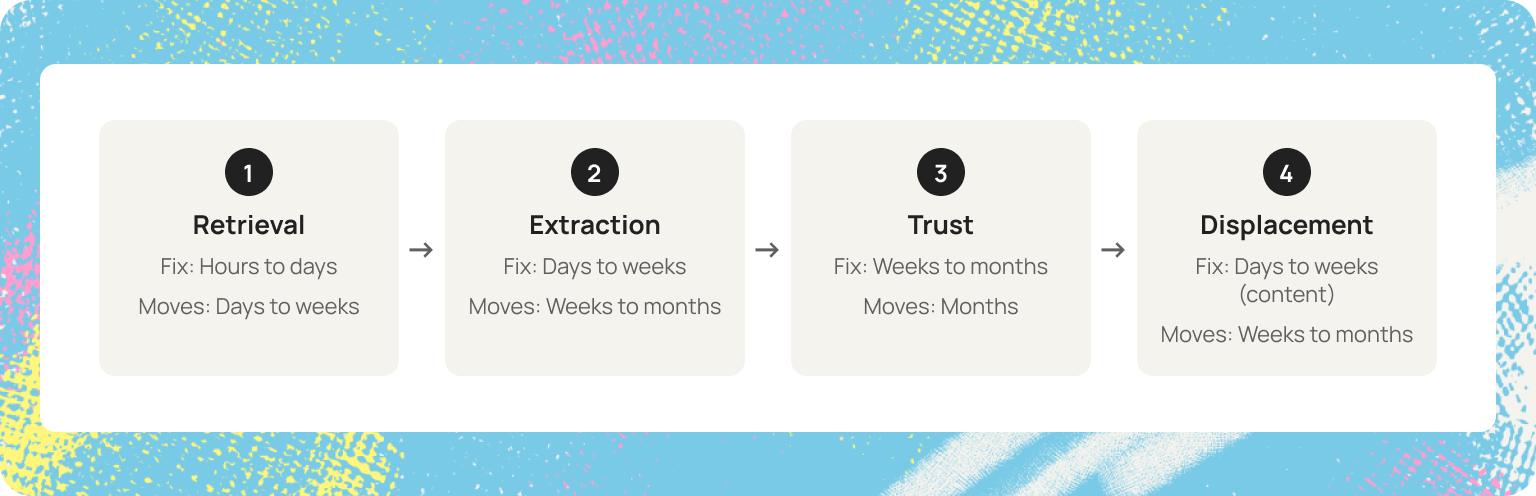
A GEO audit works through four stacked layers, retrieval, extraction, trust, and displacement, to diagnose exactly why an AI engine isn't citing you. Start with a baseline of 20-30 prompts across two or three engines, then route each finding to the layer where the first failure occurs. Most teams skip the baseline and treat every AI visibility problem the same way. This guide gives you pass/fail rubrics for each layer, real prompt examples showing the framework in action, and a ranked fix list so you know what to address first.
Teams that discounted the importance of AI search visibility a few years ago are now struggling to catch back up. Google AI Mode is up to a billion monthly users only a year after its launch. ChatGPT boasted 900 million weekly active users in February 2026. Teams are now scrambling to understand where they stand in AI search, and what to do with those findings.
The generative engine optimization (GEO) audit that most teams run gives them 10+ findings of apparently equal weight. Factors are never that evenly distributed. You might write clean, informative content, but if GPTBot can’t fetch your page, it doesn’t matter. That alone points to a clear hierarchy of critical factors.
There are only four reasons generative engines don’t cite you, and they stack. A baseline diagnosis tells you which one applies. Let’s look at how to establish that baseline, and what to do with all of the findings.
What a GEO audit measures
A GEO audit asks a narrower set of questions about what happens when an AI search engine responds to a prompt in your category. It does this in order:
- Can the engine reach your site?
- Does it lift an answer from you?
- Are you in the engine’s source pool?
- When you and a competitor are both cited, does it rank yours above theirs?
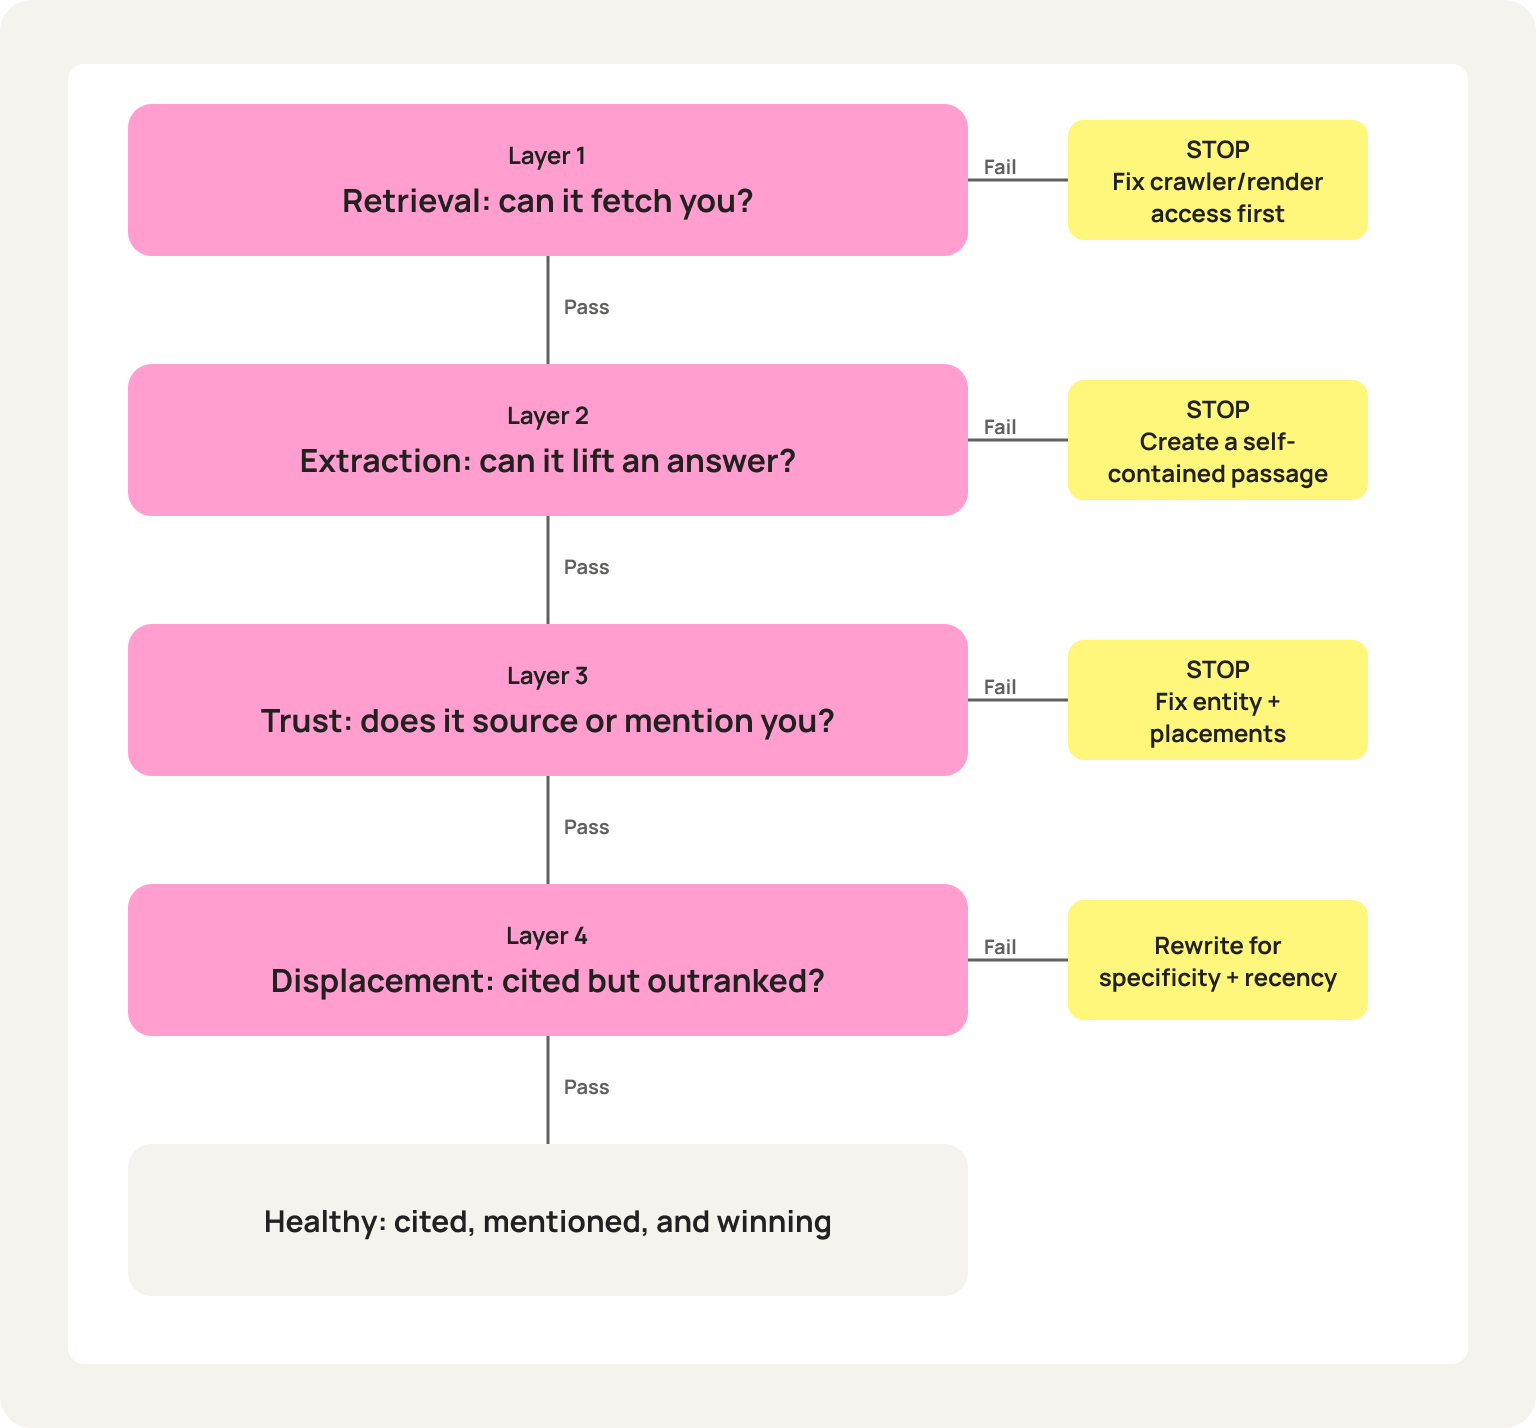
Pay attention to where the first “no” appears. That’s where your problem is, and the questions after it can wait. Those four questions are the diagnosis. What you'll observe when you run the baseline is one of four states, from fully absent to cited but outranked, because each one has a completely different fix. The issue is most teams only ask the vague “are we showing up or not” and take one holistic approach to solving that problem.
What this audit doesn’t replace
You might not have ever run a GEO audit, but you’ve likely done an SEO or content audit. Don’t assume that the boom in AI search means SEO rankings no longer matter, or that quality content is no longer important. A GEO audit should complement your existing approach.
A content audit tells you whether your page is worth reading. A traditional SEO audit tells you whether your content ranks in the search engine results pages. The GEO audit tells you why AI-powered search engines skip you in AI search results. Each one gives you a valuable answer to a different question.
Establish your baseline
Before you can run a GEO audit, you need a baseline that defines what you’re auditing against. If you skip this, every layer that comes after is meaningless.
Define your prompt set
You can’t expect your brand to appear in every question in your category. Absence is unavoidable. That’s why it’s so important to clarify where you expect to be present through prompt research. Then you can fix those unwanted absences.
Come up with 20-30 prompts, mixed across category-level, problem-level, and comparison. Track these separately from any brand-name prompts to avoid inflating the baseline. It’s safe to assume prompts with your name will almost always return you.
Choose which engines to prioritize
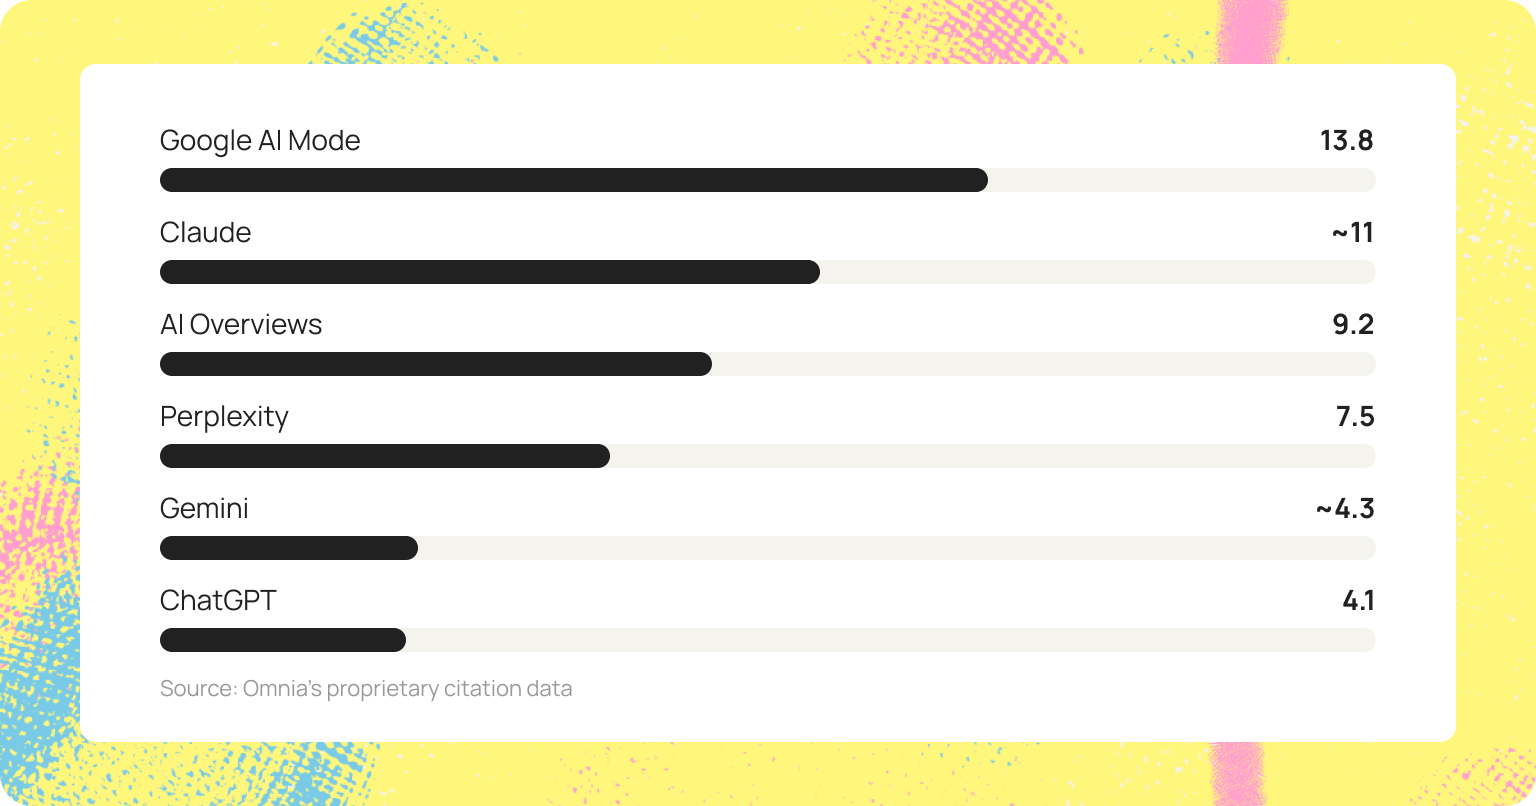
The reason engine choice matters so much is that every engine has a different citation budget, meaning the number of chances you get to be cited per answer.
Based on Omnia’s proprietary data, Google AI Mode cites an average of 13.8 domains per answer, AI Overviews 9.2, Perplexity 7.5, and ChatGPT just 4.1. Claude is the most source-hungry engine at around 11 domains per answer , while Gemini runs the leanest at approximately 4.3 . “Absent” means something fundamentally different when you have 4 chances versus 14.
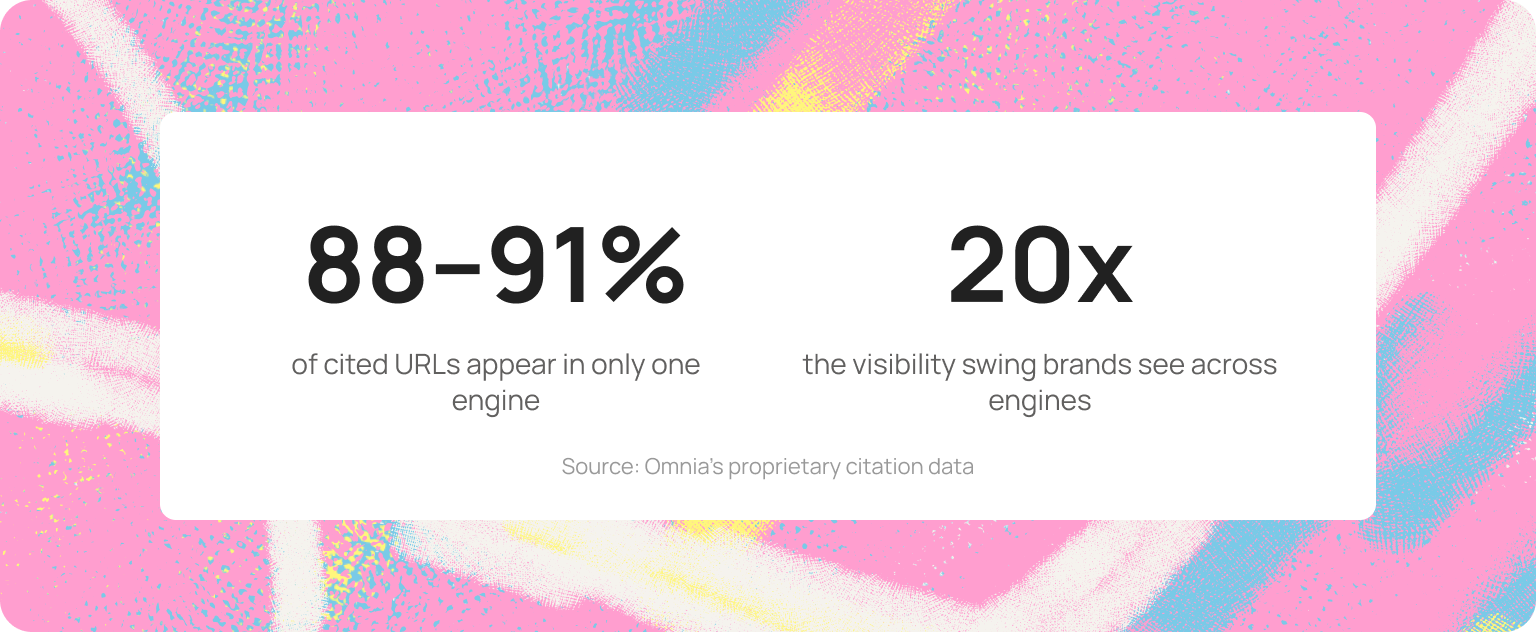
You also can't optimize one engine and assume the rest follow. According to Omnia, about 88–91% of cited URLs appear in only one engine. ChatGPT overlaps only ~50–55% with Google's engines. Brand visibility can vary by 20x or more across engines.
Pick the two or three AI search engines your buyers most commonly use, and track those. Diluting your effort across six-plus AI engines gives you a shallow picture everywhere.
Run the set by hand, consistently
You can’t run your prompt set once and call it a baseline. Perform three runs minimum per prompt per engine, always using the same wording, a logged-out account, a fresh session, and recording everything in a sheet:
- Was your brand mentioned?
- Was your brand cited with a link?
- Did that citation go to your domain or to a competitor’s?
- Which competitors appeared?
- Which sources won the citations?
This specificity helps you capture states a simple yes/no would miss, like being cited but not mentioned, and being mentioned but not cited.
You can use Omnia’s free AI visibility checker or a free GEO audit tool to get a quick idea if you don’t have the time for manual work. But it won’t properly suffice as a baseline if you’re planning to run a complete GEO audit.
Segment the baseline, don’t average it
An aggregate visibility score hides whether you appear for the buyers you want to reach. Radyant’s 2026 persona study found that prepending a persona to a prompt changed the brand mention rate by 5 percentage points or more in 28% of cases.
Adding any persona reduced average visibility from 30.0% to between 28.3% and 29.3%. That means the AI model wasn’t just redistributing share, it was recommending a tighter set of brands once it knew who was asking. In some brand-model combinations, the spread between the best and worst performing persona exceeded 20 percentage points.
This means you should run your highest-value prompts twice. Do it once plain, and once with the buyer attribute that matters in your category (company size, budget level, role, region). Make sure you log the two separately. If your aggregate score says you’re at 30% visibility but you drop to 15% when the prompt includes “for enterprise teams,” you don't have a generic visibility problem. You actually have an enterprise visibility problem that the aggregate score was hiding.
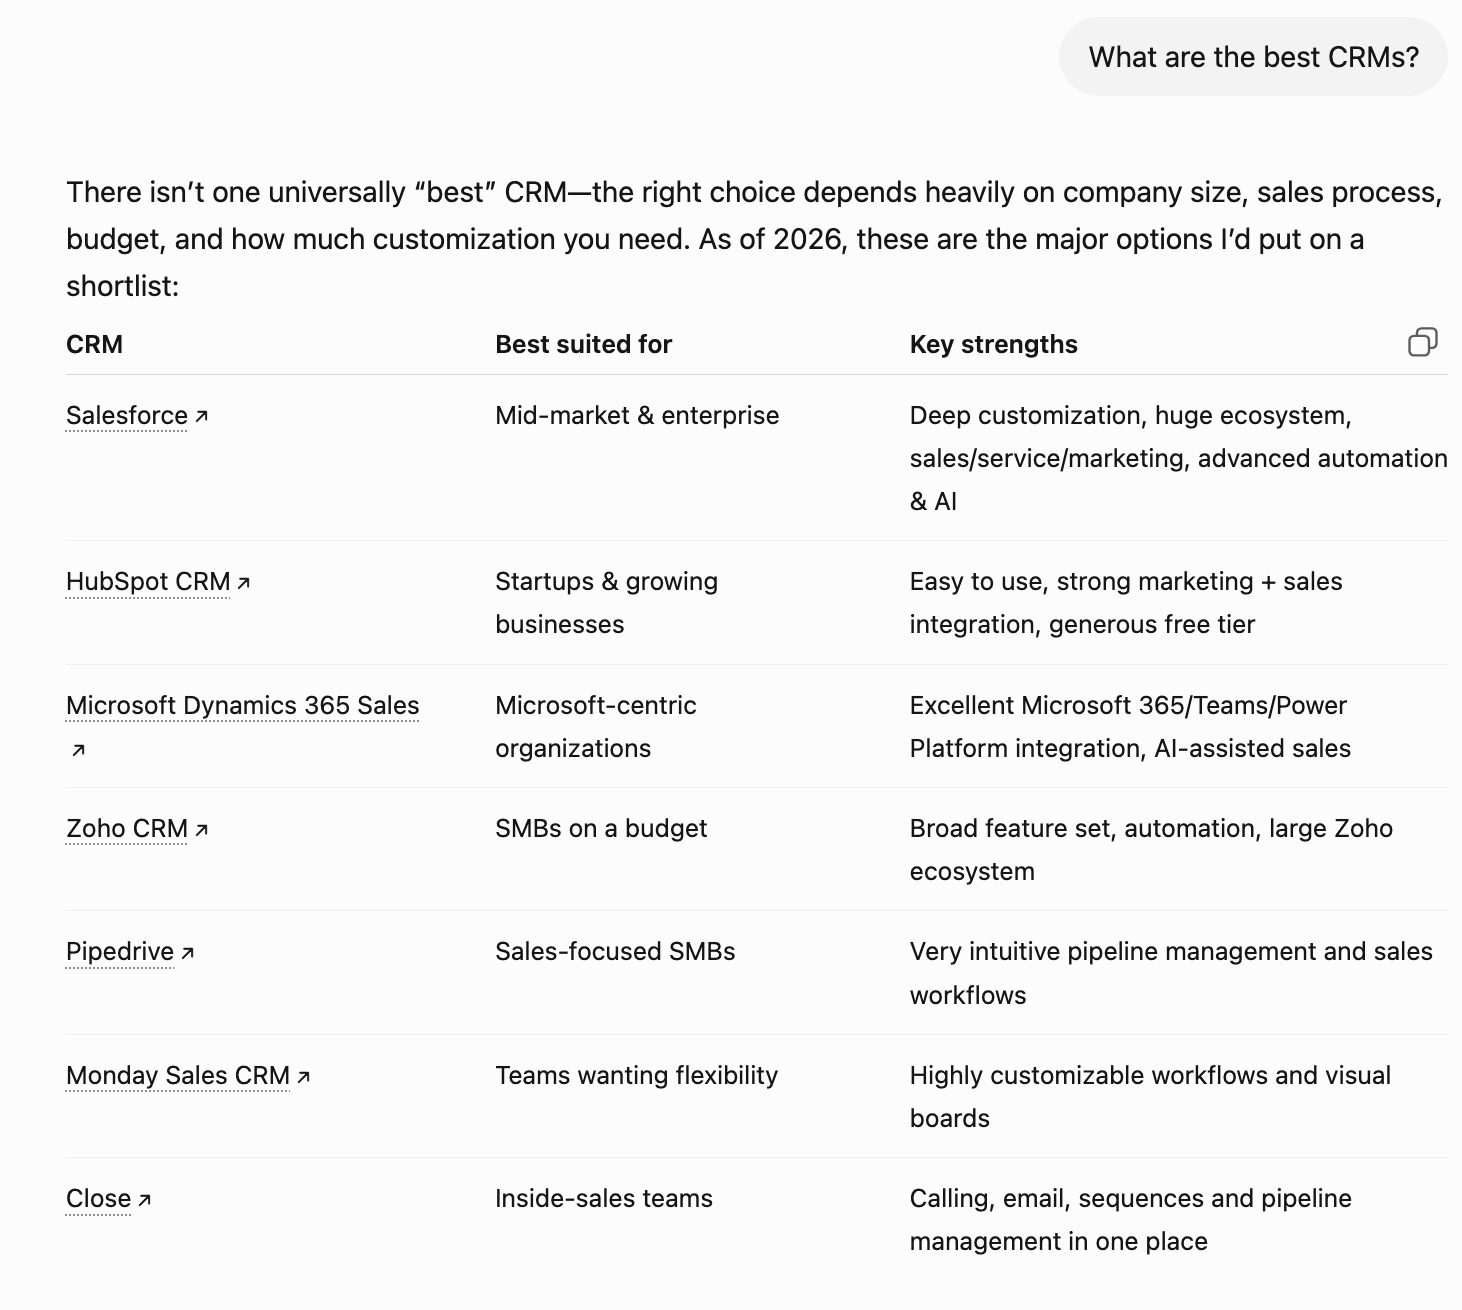
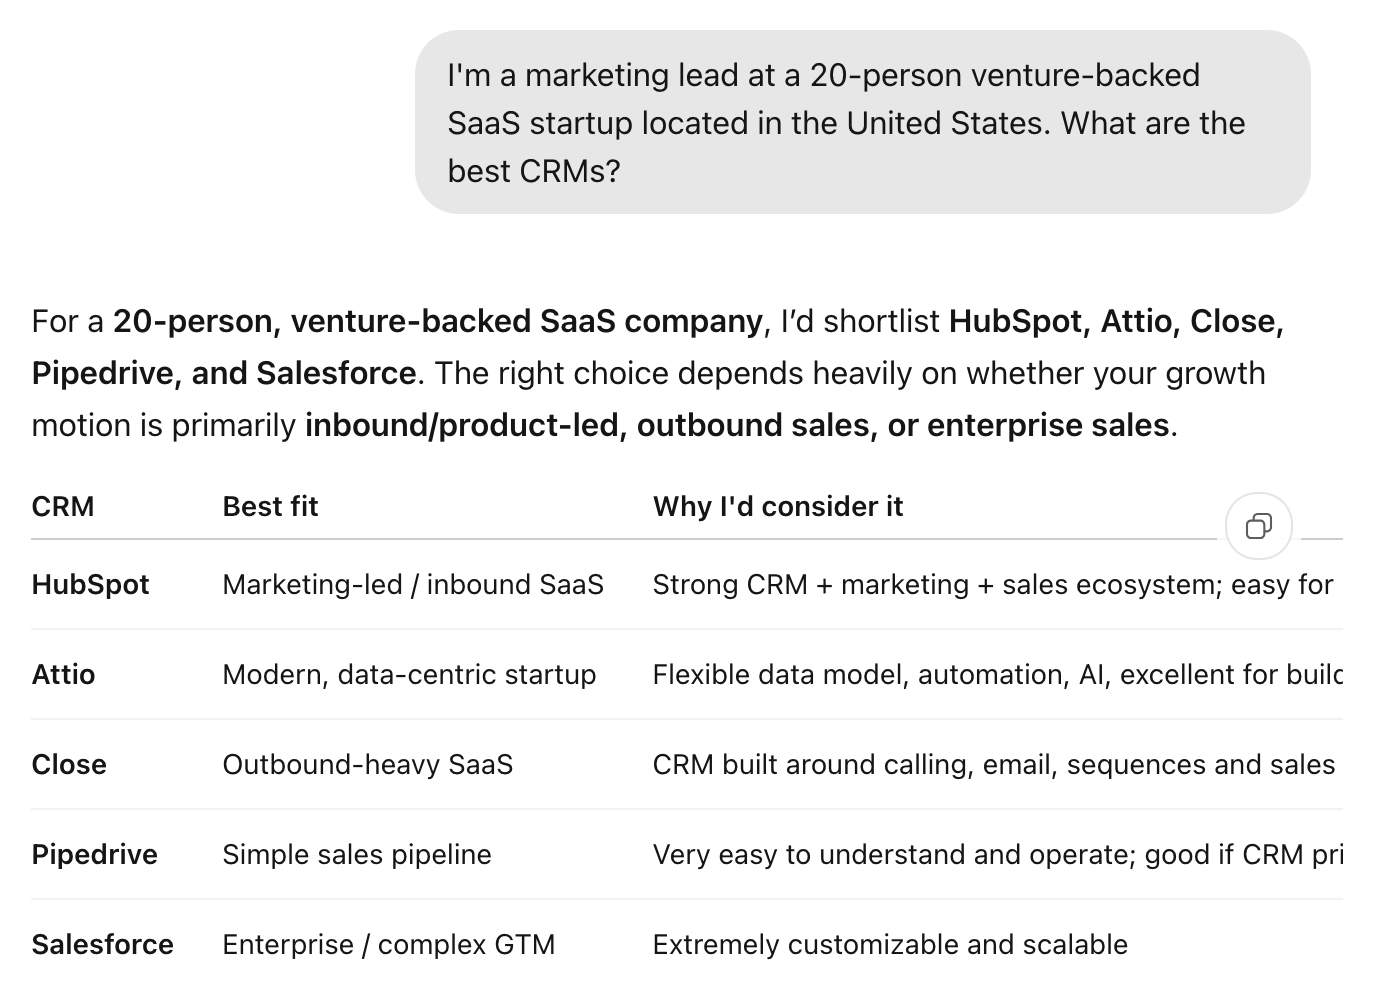
For example, adding a persona tag returns different recommendations in ChatGPT versus the generic prompt.
Read the result as one of four diagnoses
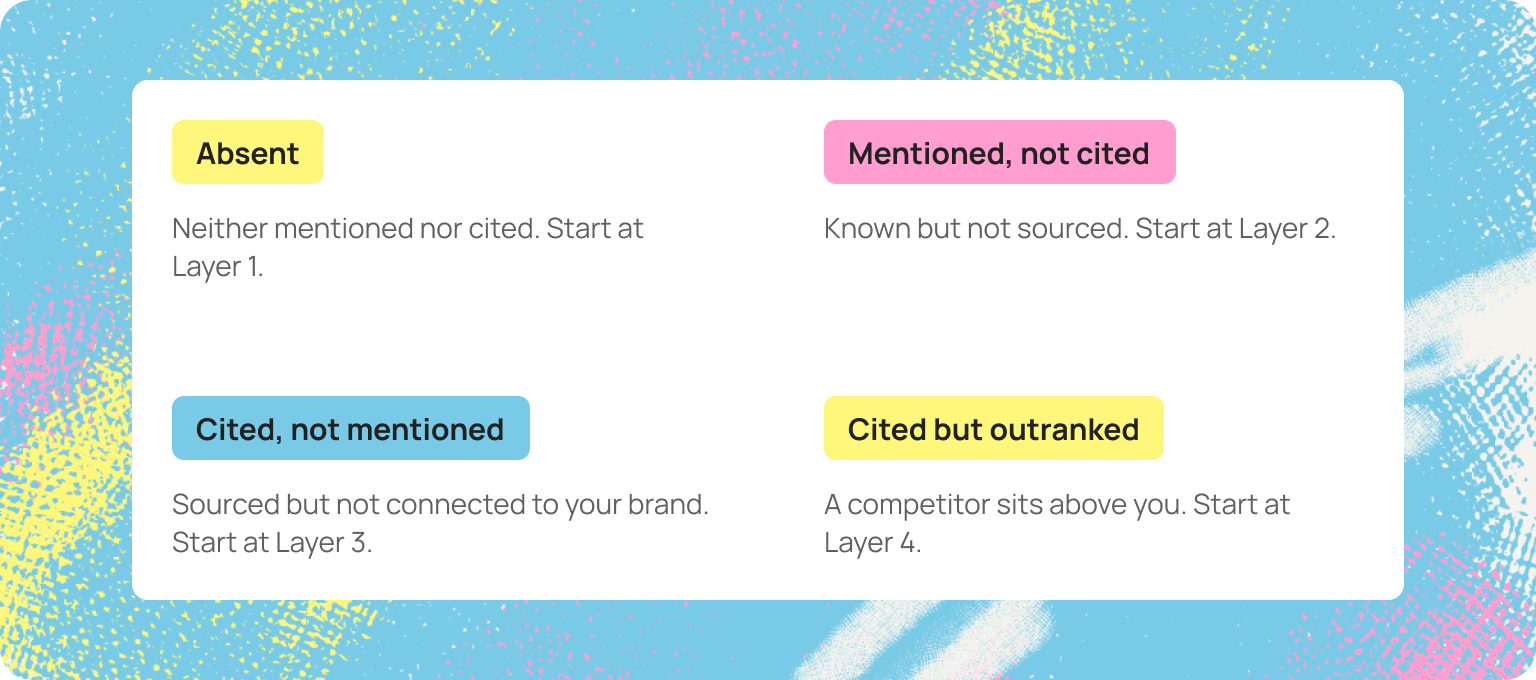
Based on your findings, you’ll get one of four diagnoses needing fixing per prompt:
- Absent: You’re neither mentioned nor cited. Start at Layer 1. If it passes, go to Layer 2. If that still passes, address Layer 3.
- Mentioned but not cited: Your name appears, but the engine links to competitors’ pages. This means your brand is known but your page isn't sourced. Start at Layer 2. If it passes, go to Layer 3.
- Cited but not mentioned: The engine pulls content from your page and cites your URL, but doesn't name your brand in the answer. You have an entity problem where your content is good enough to be sourced, but the engine isn’t connecting it to your brand identity. Start at Layer 3.
- Cited and mentioned, but outranked: You appear, but a competitor is positioned above you. Start at Layer 4, but only after confirming Layers 1–3 are clear.
If you’re cited, mentioned, and winning the prompt, this is the ideal state. No layer is needed because your prompt is healthy, so you can move on.
Layer 1. Retrieval: Can an engine actually fetch you?
Don’t assume that because you’ve done a technical SEO audit your page is good to go. An SEO audit checks Googlebot and Bingbot while Layer 1 checks the AI crawlers. A page can pass an SEO audit and fail Layer 1 because the AI crawlers are blocked separately.
Always start here, it’s the easiest and cheapest portion of a GEO audit to check.
Check crawler access (and the WAF block robots.txt hides)
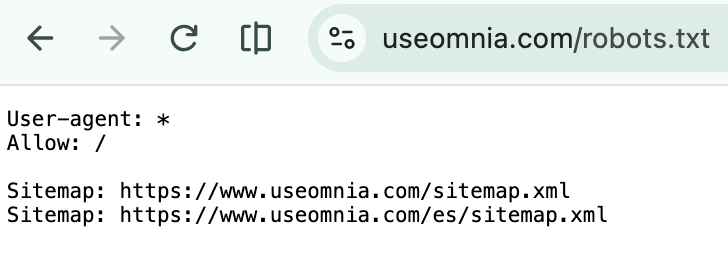
“robots.txt” dictates which paths compliant crawlers may request on your website. Open https://yourdomain.com/robots.txt in your browser and look for two things:
- A broad Disallow: / under User-agent: * (which blocks every crawler including AI bots)
- Explicit blocks on the AI-specific user-agents like GPTBot, ClaudeBot, PerplexityBot, Google-Extended, and OAI-SearchBot
As an example, Omnia’s robots.txt is the simplest correct version. Every crawler from Googlebot to GPTBot to ClaudeBot to PerplexityBot can fetch every page. Nothing is blocked. The sitemap lines help crawlers discover the full site, including the Spanish-language pages.
Still, a clean robots.txt doesn't mean crawlers can actually reach you. The block teams miss most often happens at the CDN or WAF level. Cloudflare's Bot Fight Mode, DataDome, Imperva, or Akamai Bot Manager can challenge or block AI crawlers before the request ever reaches your origin, and robots.txt looks fine the whole time
You can test this with a single command. Open Terminal on your Mac and enter “curl -A 'GPTBot' -I https://yoursite.com/”
A 200 response means the upstream is open. A 403 or a redirect to a JavaScript challenge page means the WAF is blocking before robots.txt is even read. Run the same test with ClaudeBot and PerplexityBot as the user-agent.
Then check your server logs for the last 30 days. If zero GPTBot, ClaudeBot, or PerplexityBot fetches appear despite an open robots.txt, something is blocking upstream of your origin.
Verify the content exists without JavaScript
You can easily confirm the primary content exists in server-rendered HTML rather than being injected client-side.
Simply follow these steps:
- Open your target page
- Right-click anywhere and click “Inspect”
- On a Mac, press “Command” + “Shift” + “P”
- Type “Disable JavaScript” then hit enter
- Reload the page
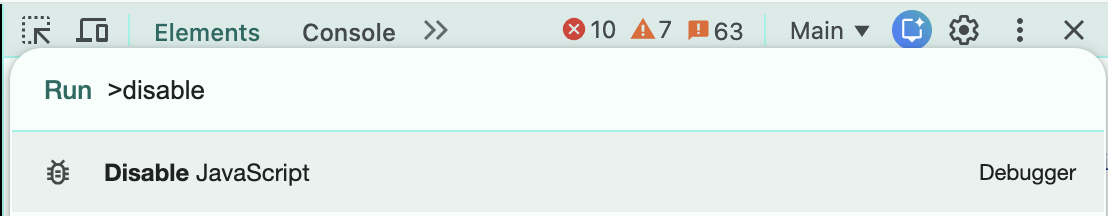
If your page loads fine, then you’ve passed this step. If the content disappears, you’re seeing what the engine sees, a blank page. It doesn’t run your JavaScript, so anything injected client-side is invisible to it.
Answer the llms.txt question honestly
You'll see llms.txt mentioned in GEO discussions. It’s a proposed standard, a Markdown file at your site root (yourdomain.com/llms.txt) that gives AI systems a curated list of your most important pages. Jeremy Howard proposed it in September 2024 and it’s gained traction through community adoption rather than formal standardization.
However, the major AI crawlers aren’t reading it in any meaningful volume. An Ahrefs study of 137,000 domains found that 97% of valid llms.txt files received zero bot requests in a month. Google has also confirmed AI Overviews and AI Mode require no special AI file.

The file grants nothing and blocks nothing. No crawler is obliged to read it, and it’s also not a substitute for any of the checks above. Feel free to add it, but don’t treat it as a strategic fix and don’t let anyone sell it to you as a complete GEO strategy.
Layer 2. Extraction: Can an engine lift an answer out of the page?
You’ve landed in Layer 2 because your content is readable. Yet, you’re still absent, or your brand is getting mentioned but you’re missing that valuable citation. Here’s what to do.
Run the passage test (first 50–100 words, question-shaped heading)
Check whether a self-contained answer exists in the first 50–100 words under a question-shaped heading. The answer should be readable without any context above it. That means no pronouns that need resolving, no “as mentioned earlier,” and no references to the previous section.
A controlled 2026 study found structured documents (answer-first, question headings, self-contained passages) achieved 2.6x higher citation rates than unstructured versions with identical facts and word count.
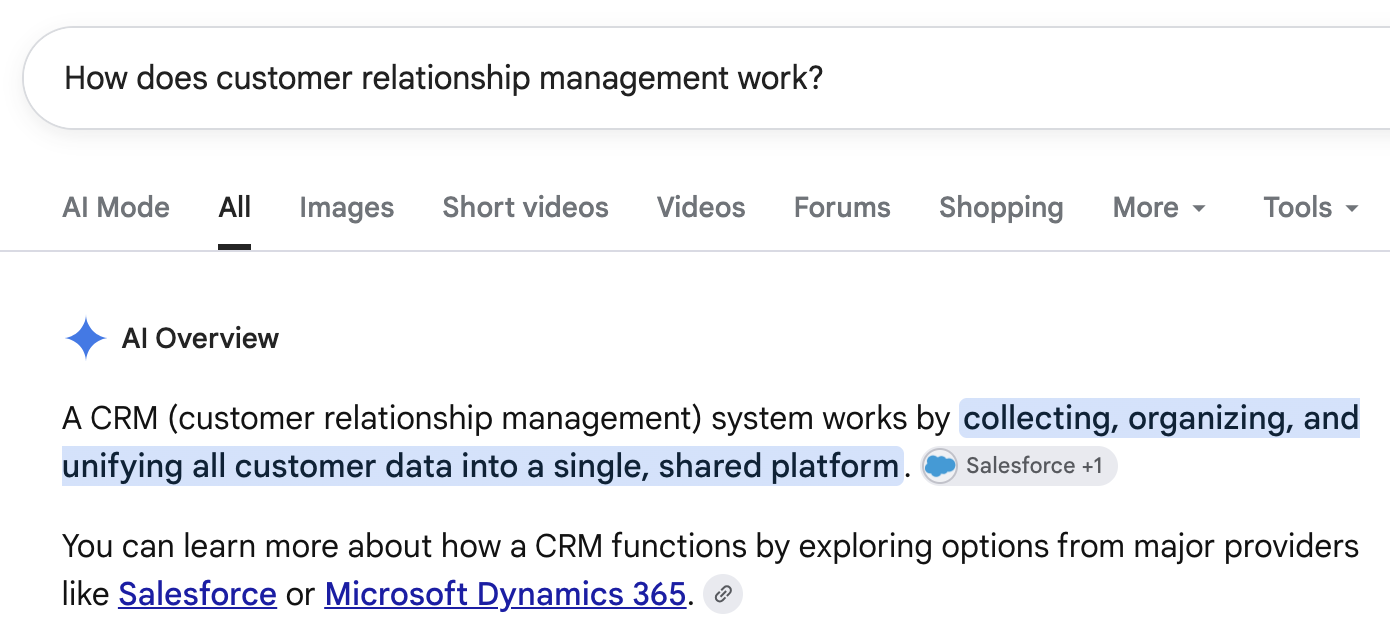
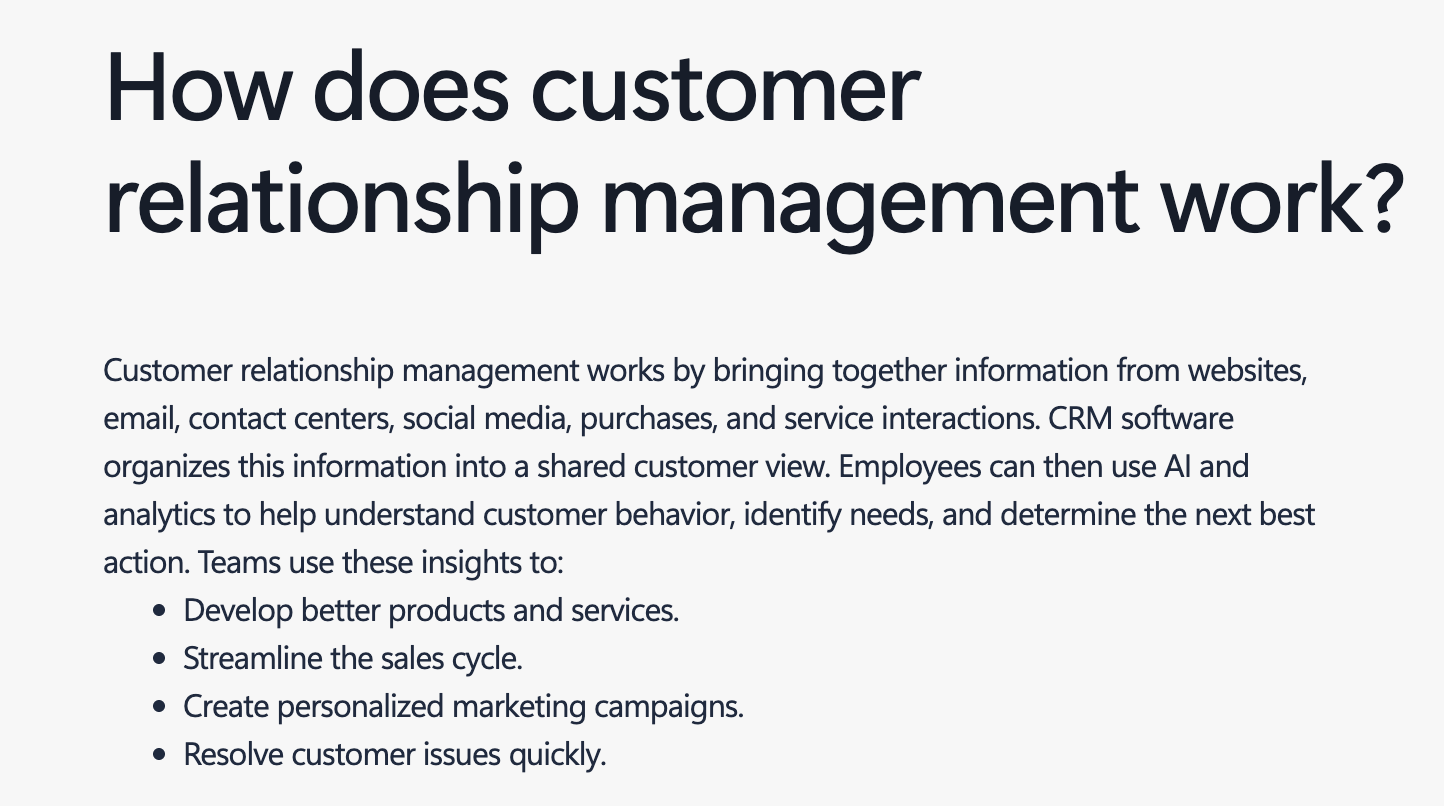
For example, if you Google “How does customer relationship management work?” SalesForce and Microsoft Dynamics own the answer.
Microsoft's page that won the citation opens with a question-shaped heading that matches the prompt verbatim, then answers it in the first two sentences with a self-contained definition. The sentences are short and declarative, each one a standalone claim an engine can lift.
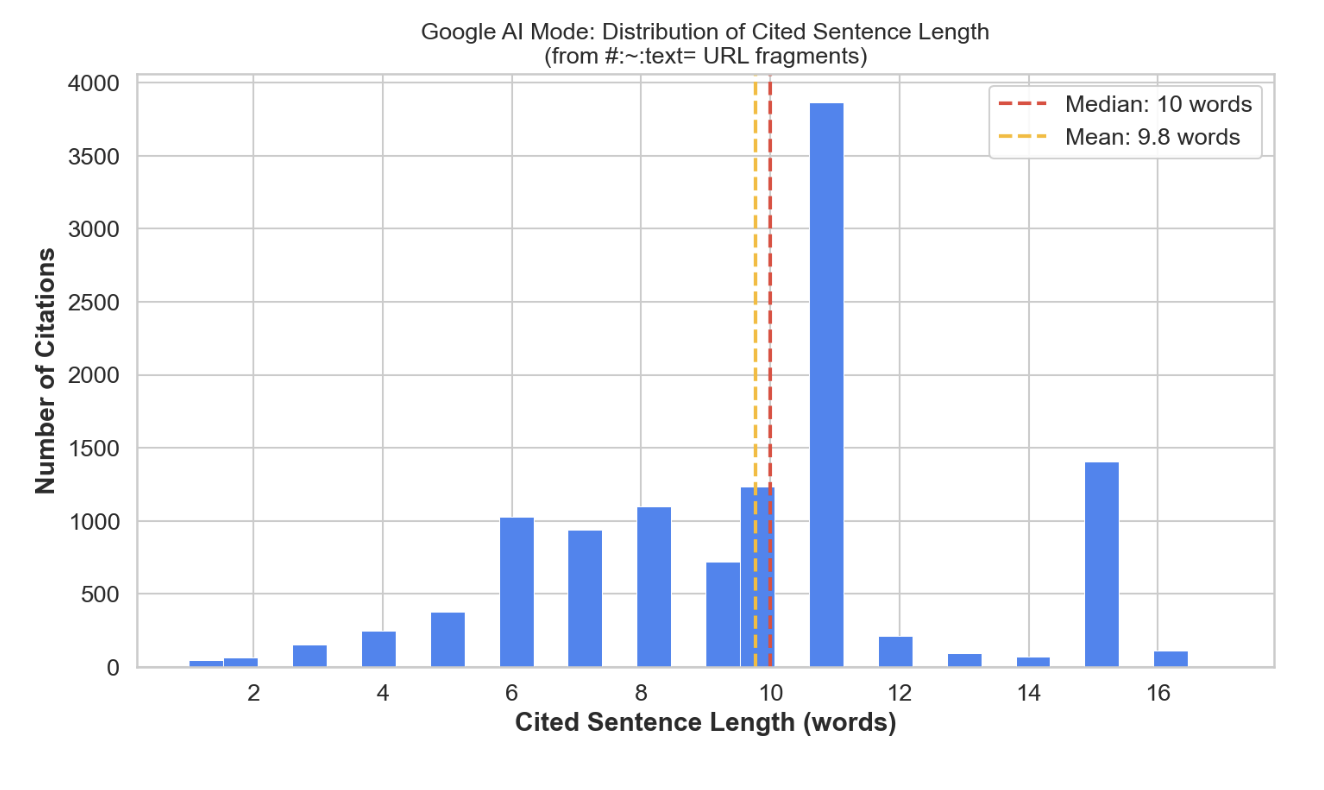
The reason the passage test works is that engines don't paraphrase your content, they extract exact sentences, and only short ones. Daniel Shashko reverse-engineered 42,971 AI citations and found that the median cited sentence is 10 words. 92.4% of cited sentences fall between 6 and 20 words. Not a single cited sentence in the entire dataset exceeded 17 words. If your key claim is buried in a long, hedged, multi-clause sentence, the engine will never lift it.
There's also a lead bias. 75% of cited sentences appear in the first half of the source page. So, if your answer is in section 5, it's in the lowest-probability citation zone.
Validate structured data (and know its limits)
Validate the structured data markup that helps engines parse your page: Organization, Article, FAQ, and Product. There is no AI-specific schema markup, though, and schema alone won’t earn you citations.
But content structure itself like lists, tables, and headings do matter. Per Shashko’s study, pages with structured content achieved a 91.3% sentence-match rate versus 39.3% for unstructured pages. Structure pre-chunks your content for the engine's retrieval pipeline. Generative AI platforms pull from these structured passages to build their AI responses.
Omnia’s proprietary data backs this up at the content-type level. Review and comparison pages earn the best average citation position in Perplexity (3.1) and pull higher citation share in ChatGPT. In Gemini, blog and article pages plus review and comparison pages make up 45% of all citations while product, pricing, and FAQ pages are effectively uncitable. The engines aren’t picking pages at random. They're picking pages that are structured to be lifted.
That’s structure on the page. Schema is structure in the markup, and Google moves the goalposts on what it rewards often enough that tracking those changes is part of the audit itself.
Google deprecated FAQ rich results from Search in May 2026. FAQPage schema is still a valid type that Google crawls and processes, but Google’s own guidance says no special structured data is required for Google AI Overviews or AI Mode.
Keep your schema if you have it. It costs nothing and it helps engines understand your page structure. But don't treat it as a citation strategy. The content itself is what earns the citation. Schema just makes it easier to find.
Layer 3. Trust: Does the engine source you, or someone else?
Many teams will confirm they’re being mentioned and count that as a win. Or see that an LLM cited their page and move on. Both of these use cases in isolations are still considered “failures” and pose large GEO challenges.
A citation without a mention means the engine isn’t connecting your content to your brand, which is an entity problem. A mention without a citation means your brand is known (a win), but your page isn’t in the source pool, which is a sourcing problem.
These two states land here, and the fix is mostly the same.
Log every domain the engine cites
Keep track of every domain the engine cites where you’re absent. This matters for both failure modes, but for different reasons. If you’re mentioned but not cited, the source list shows you which domains are winning the citations your brand should be getting. Consider those your placement targets.
If you’re cited but not mentioned, the source list shows you which domains the engine trusts in your category, which tells you where your entity needs to be consistent.
A citation eligibility score measures how likely your page is to be selected and attributed as a source when an AI engine generates a response. Eligibility depends on relevance fit, extractability, trust and verifiability, and reliable retrieval access. It’s also prompt-dependent. A page can be eligible for “what is X” prompts but not for “X vs Y” prompts if it lacks comparison structure
This audit isn’t telling you what to write. It’s telling you where you need to be. If the most frequently cited sources are third-party sources, you need to secure placements on those domains. If you’re being mentioned across multiple sources but they all describe you differently, you have a digital PR problem, not a content problem. The fix is consistent messaging across the publications the engine reads, not more pages on your own site.
Check your entity across every surface
If you’re cited but not mentioned, this is your primary fix. The engine can lift your content but can't connect it to your brand, which means your entity is either ambiguous or inconsistent across the surfaces the engine uses to verify identity.
Entity disambiguation happens when the AI system must choose the correct entity when there are multiple choices sharing similar names. It’s how apple the fruit gets differentiated from Apple the company.
Double-check that all of these are similar across directories and review platforms:
- Brand name and spelling
- Industry or category descriptor
- Product naming
- Founding details (year, location, founders)
- Canonical domain and URL structure
The schema you validated in Layer 2 is the on-site entity fix where you tell the engine who you are on your own pages. This is where you tackle the off-site entity problem.
If your site says one thing and the rest of the web says another, the engine trusts the consensus, not you. An identity crisis across surfaces is harder to fix than a missing schema tag because you don't control most of those surfaces. It’s also more impactful, because the engine uses external sources and training data to confirm who you are before it attaches your name to a citation.
This is the slowest layer to fix and the one with the longest lag between action and movement.
Layer 4. Displacement: Are you cited but still losing?
This is the narrowest and most advanced diagnosis. If you’re earning a citation and mention, though not the number one recommendation, you’re still in good shape. This is the only layer where “write better content” is a real solution, but only if Layers 1–3 are clear.
Here’s where to go from here:
- Check what's outranking you: If the citation positioned above yours is a third-party roundup, review site, or directory, you can’t rewrite your way up a list someone else wrote. The ordering is the editor’s call. That’s a Layer 3 problem, so go back.
- Check if the advantage is structural: If the brand above you owns the platform (like how Salesforce owns Slack) or has years of name recognition, the engine positions them higher because it trusts them more, not because their passage is better. Target the prompts where your positioning wins and accept that the generic share of voice belongs to the incumbent.
- Write better content: Compare your cited passage to the competitor’s on specificity, recency, and prompt-fit. A passage that says “tools for tracking AI visibility across 12 engines” beats one that says “tools for AI search visibility.” A passage citing 2026 data beats one citing 2024. A passage that addresses the prompt as asked beats one that addresses the topic generally. Rewrite to win on the axis where you’re losing, then re-test.
- Be the most recent source: Engines favor current content. If your competitor's passage cites 2024 data and yours cites 2026, that alone can flip the ranking. Update your most-cited pages regularly with current data, pricing, and features.
- Win on breadth: If you can’t win one prompt, win more. Track your citation share across your full prompt set, not just the prompts where you’re outranked. Being cited across 10 prompts while your competitor wins 3 is still a net win.
- Build entity authority over time: Consistent entity signals like Wikipedia, backlinks, directory listings, and review platforms compound. The engine positions trusted brands higher, and trust builds slowly. This is the long game that supplements the immediate passage rewrite.
See the framework in action
We ran four prompts across ChatGPT and Google AI Mode using a consistent persona: “marketing lead at a 20-person venture-backed SaaS startup.” Each prompt exposed a different failure state from the audit. Here’s what we found, organized by what went wrong.
Mentioned but not cited
We started with: “I'm a marketing lead at a 20-person venture-backed SaaS startup. What are the best CRMs?”
In ChatGPT, HubSpot and Attio won citations from their own domains. Pipedrive and Close were both mentioned, but neither earned citations from their own domains. Pipedrive’s citation came from a third-party comparison page. Close's citations came from a third-party "best CRM for founder-led sales" page and an Attio alternatives page. Both brands are known enough to be mentioned, but neither had a page the engine chose to source.
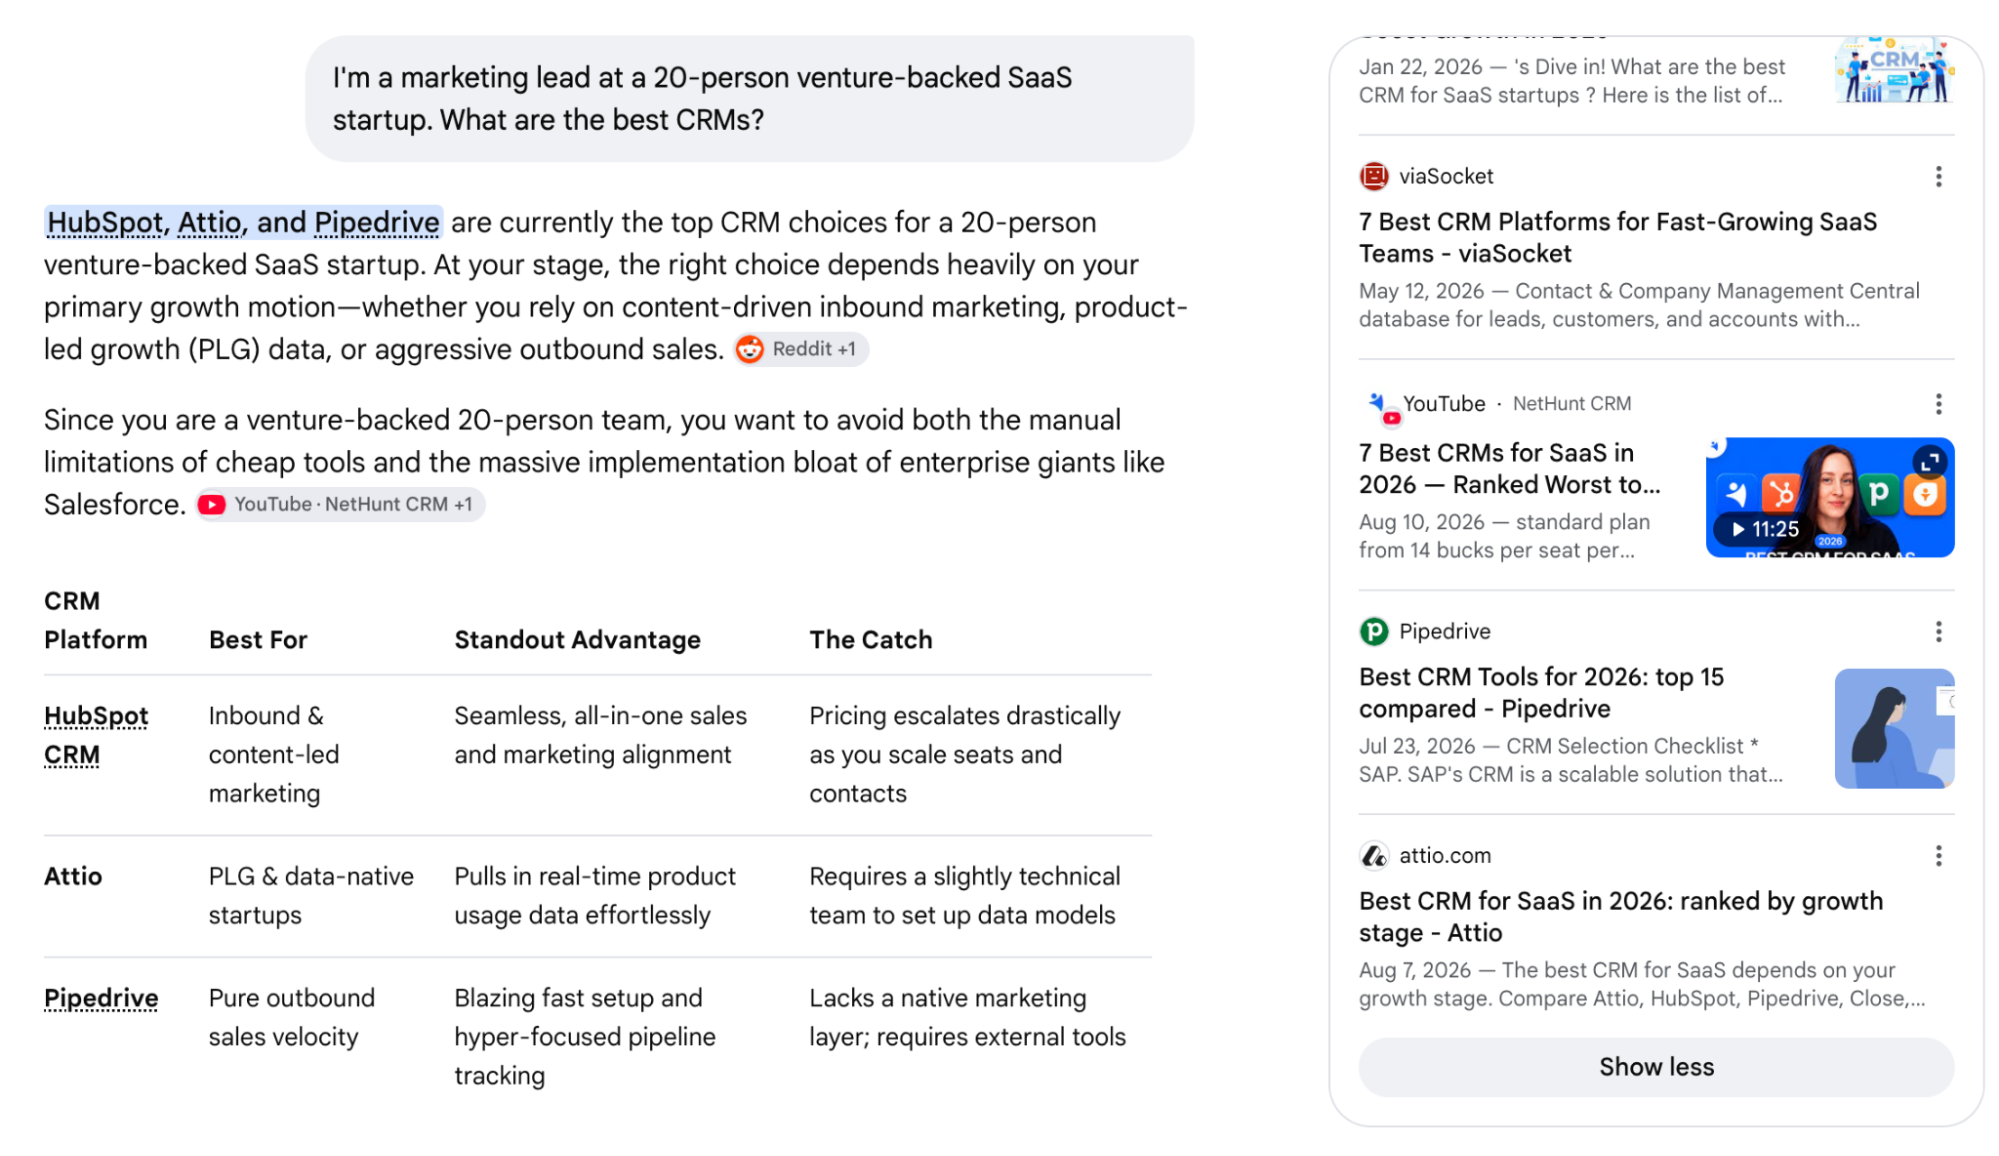
In Google AI Mode, the picture flipped. HubSpot ranked first but earned zero citations from its own domain even though Pipedrive still did. Every citation came from a Reddit thread, YouTube videos, a LinkedIn roundup, and third-party articles. The engine recommends HubSpot but doesn’t source it. Same brand, same query, different engine, different failure mode.
If you’re mentioned but not cited, start at Layer 2. If you don't have a page that answers the query, create one. If you do have one and it’s extractable, go to Layer 3. The engine doesn’t trust your page enough to cite it, and the fix is placements and PR, not more content.
Cited but not mentioned
In the same AI Mode query, OneSuite was cited supporting Pipedrive’s description but wasn’t named in the answer at all. The engine found OneSuite’s content useful enough to cite, but didn’t name them as a recommendation. This could happen to you as well for two reasons:
- An entity problem: The engine can’t connect the content to the brand
- A trust problem: It can connect them but doesn’t consider the brand recommendation-worthy.
You can tell by checking whether the engine ever mentions you in other prompts. If it does, you have a trust problem. If it doesn’t, it’s an entity issue.
Cited and mentioned, but outranked
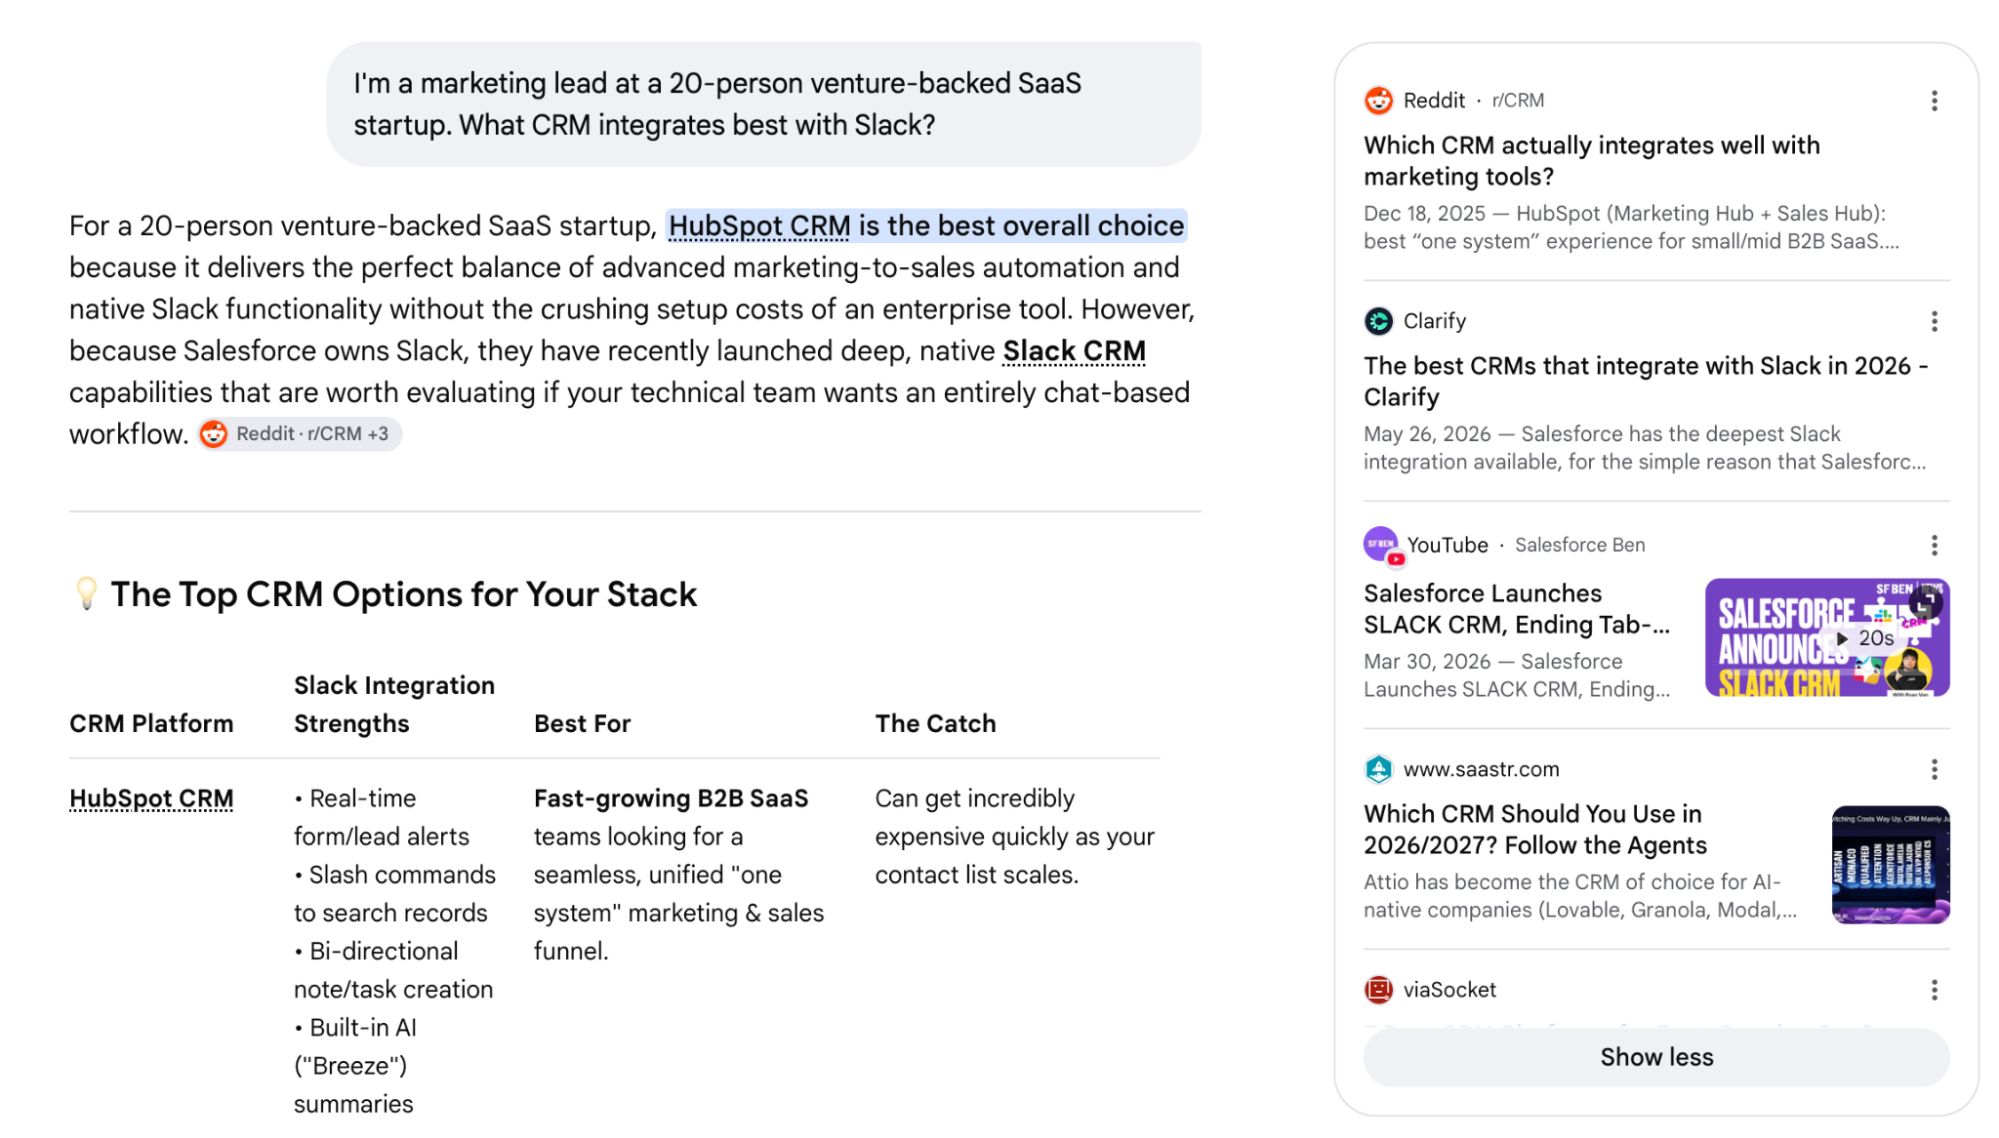
We ran two versions of a Slack integration query: “I’m a marketing lead at a 20-person venture-backed SaaS startup. What CRM integrates best with Slack?” and the generic “What CRM integrates best with Slack?”
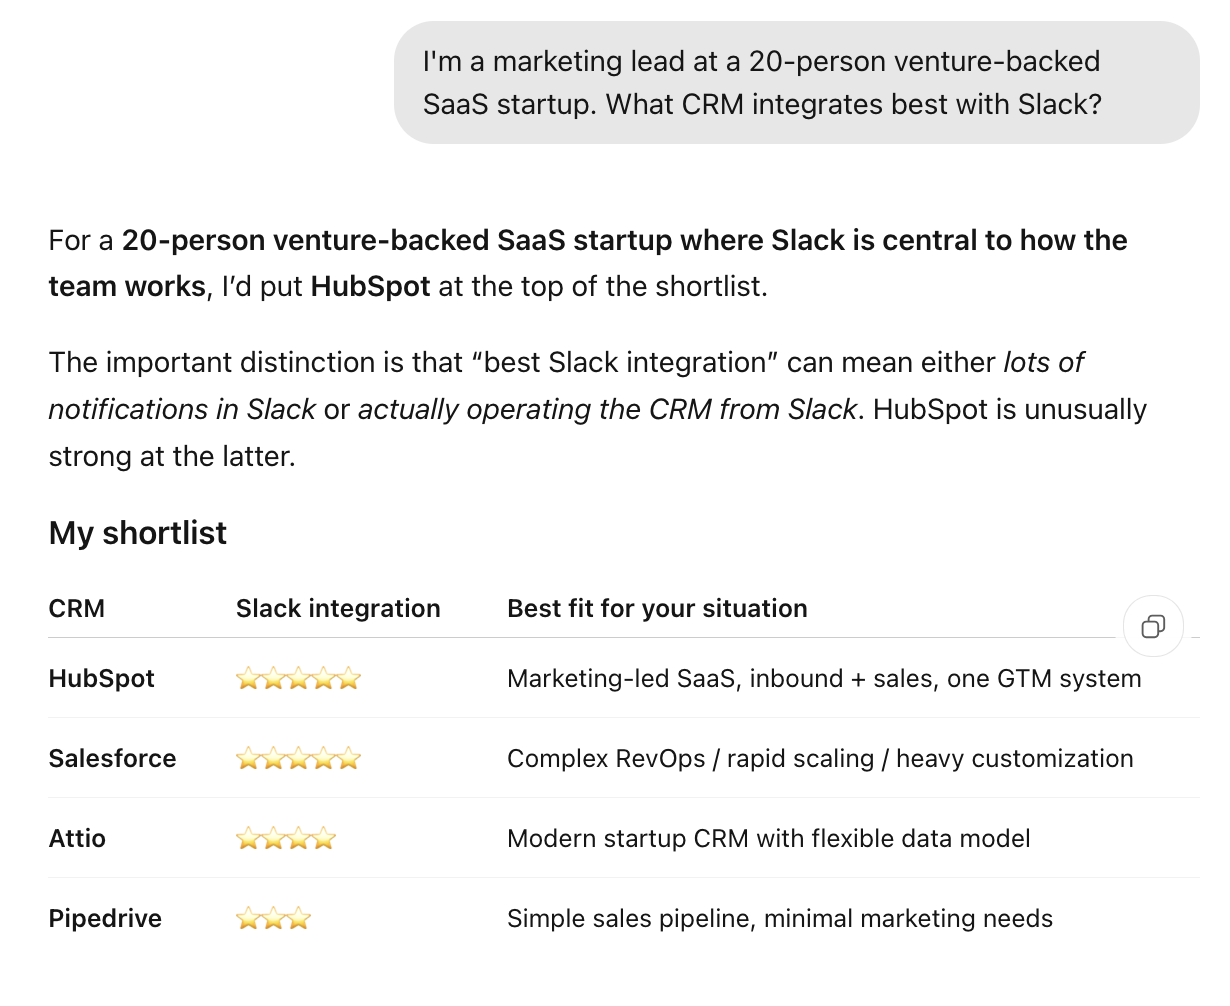
With the persona, HubSpot won in ChatGPT, cited from its own Marketplace and Knowledge Base pages. Without the persona, Salesforce moved to the top in both engines, cited from its own Slack integration page. Salesforce owns Slack, so their integration page is the authoritative source for the generic query.
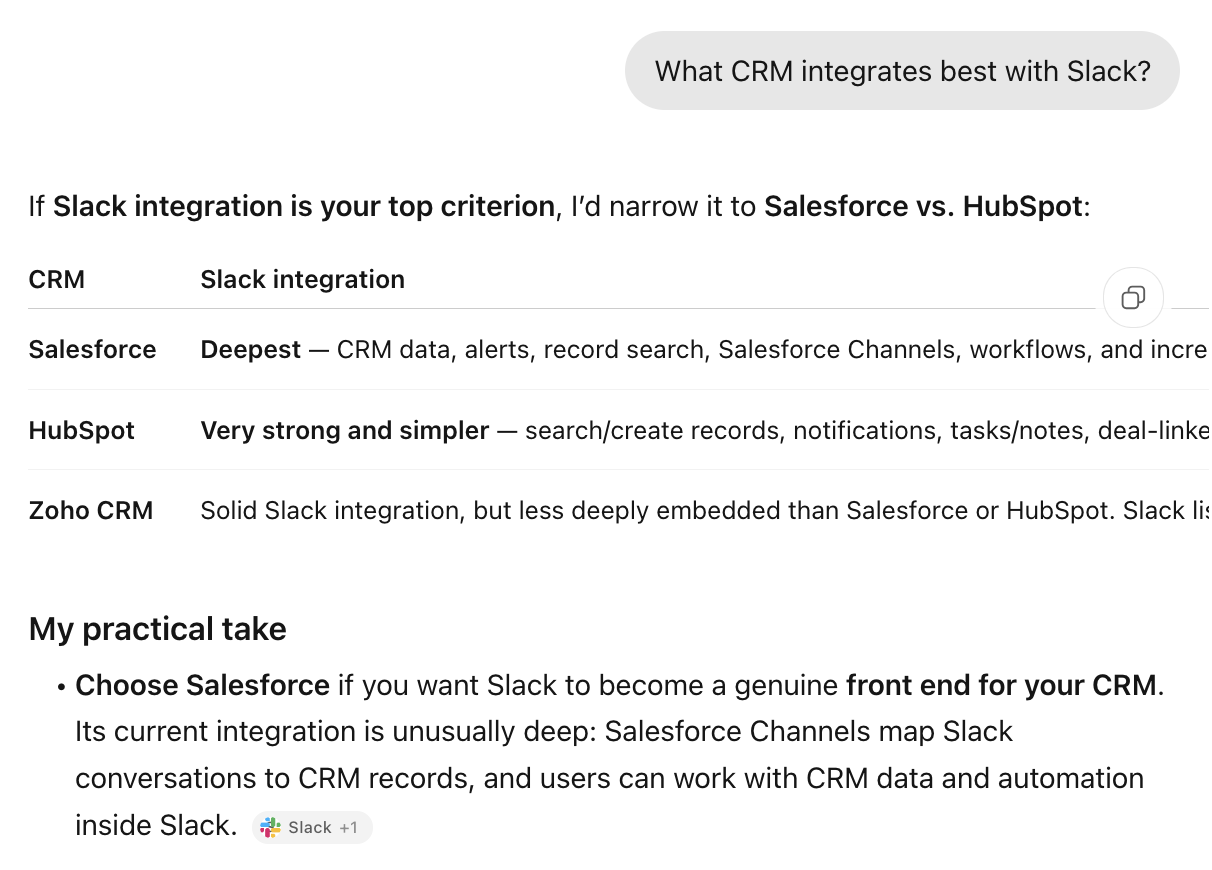
No amount of rewriting HubSpot’s Slack integration page displaces Salesforce for the generic prompt. That’s a structural advantage baked into the ownership.
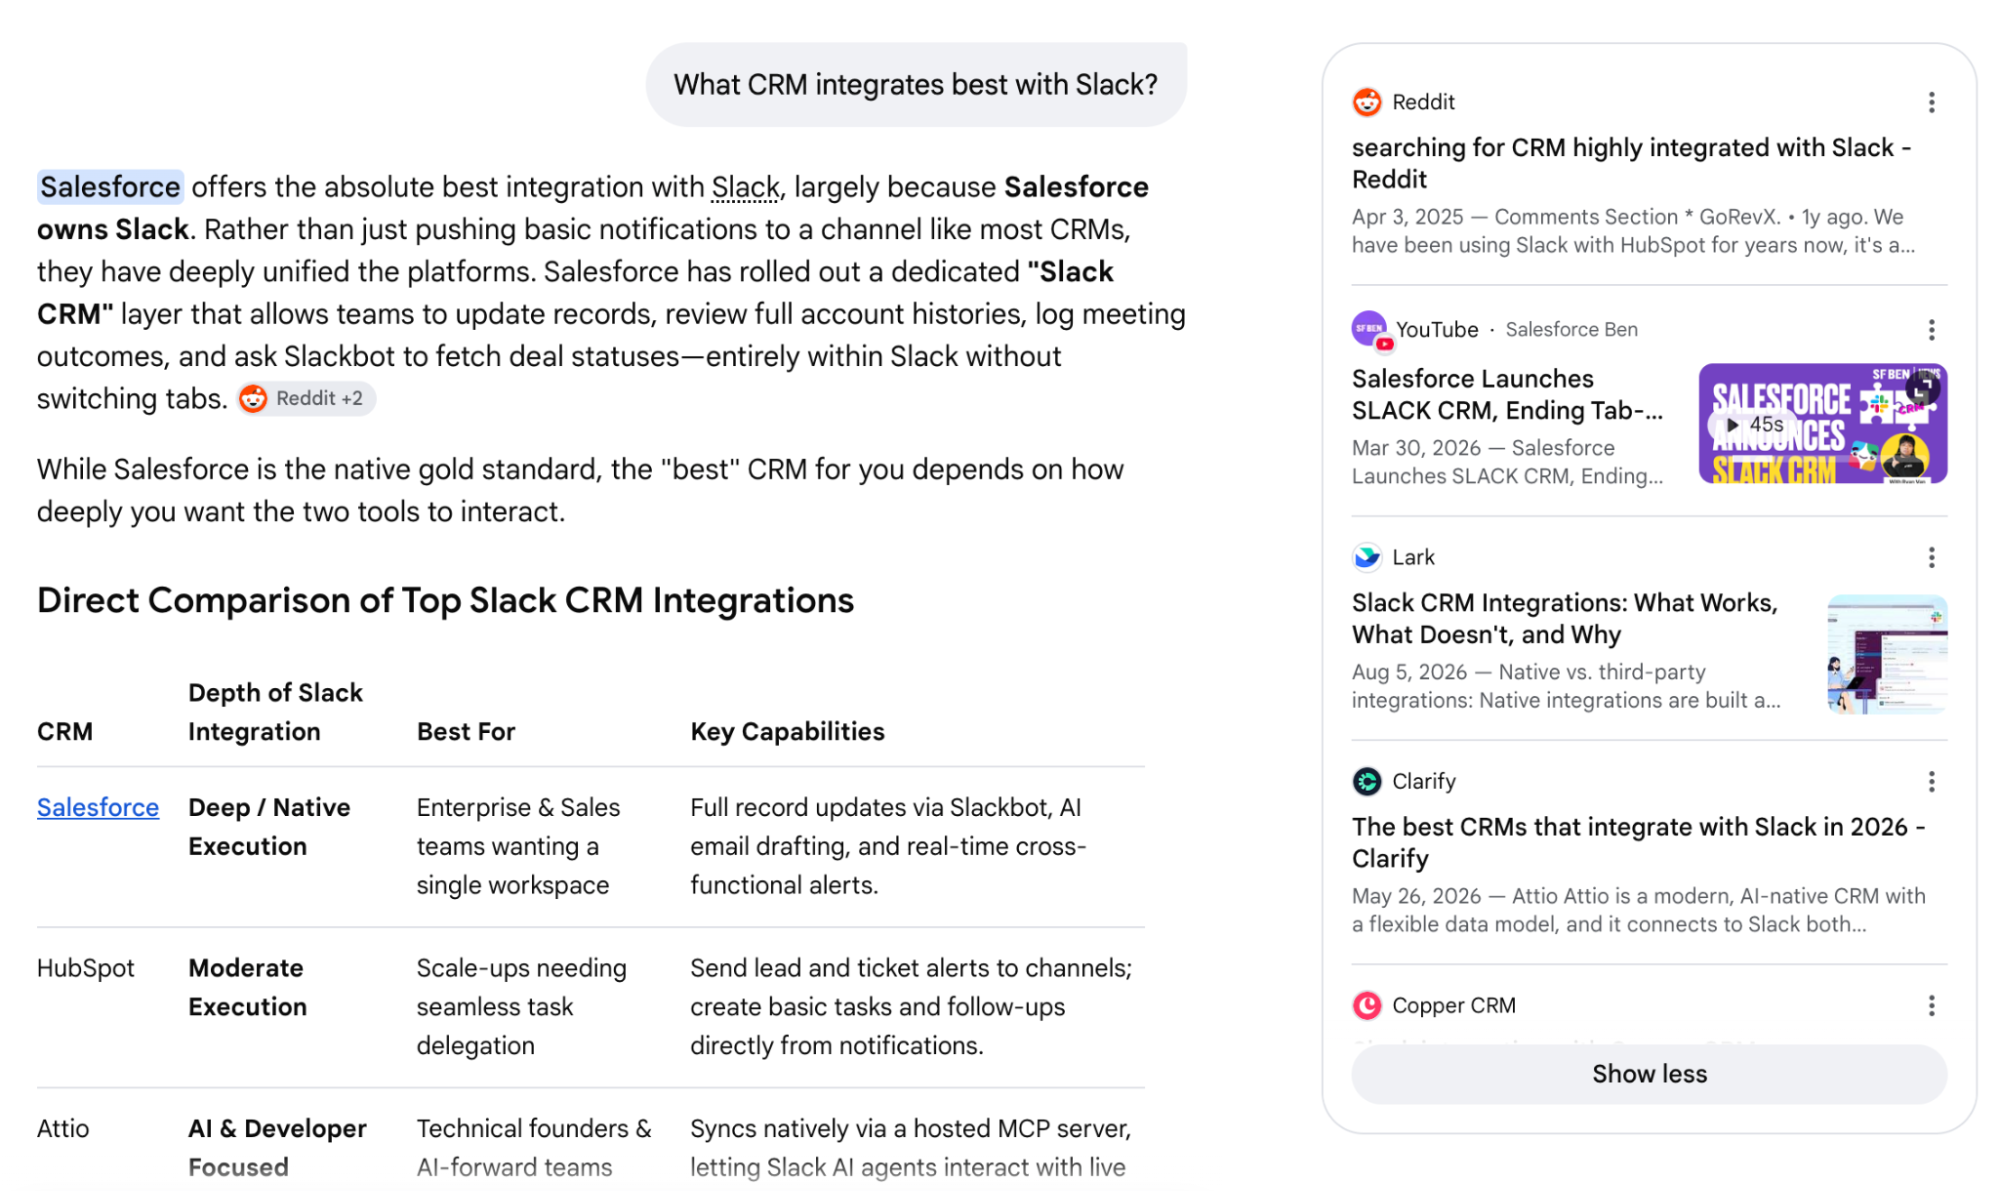
The fix, then, is to target the prompts where your positioning wins (the persona-specific ones) and accept that the generic prompt belongs to the one with the structural advantage.
The healthy state
Attio was the only brand cited from its own domain in both engines for the CRM query. It built purpose-built pages like “best CRM for startups” and “best CRM for 2026” and both engines found them. That’s the healthy state: cited and mentioned, from your own domain, across engines.
The persona changes everything
We ran two versions of a comparison query: the persona-tagged “I'm a marketing lead at a 20-person venture-backed SaaS startup. What are the best CRMs?” and the generic “What's the best CRM for a small team?”
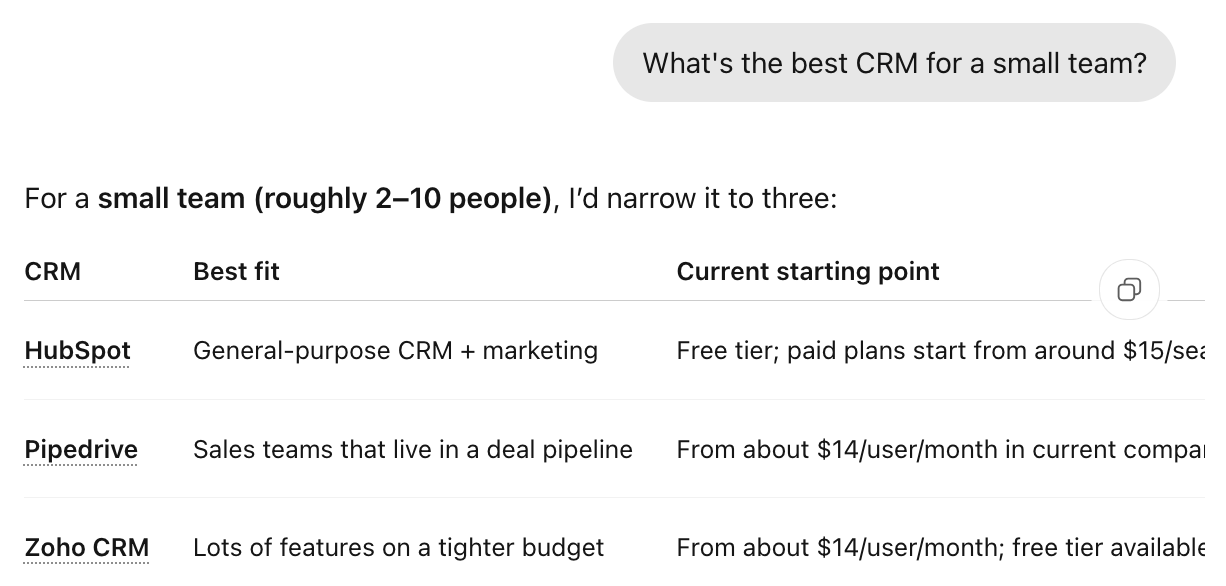
Attio won its own citation in the persona query across both engines. In the generic query, Attio disappeared entirely. It wasn’t mentioned or cited. The persona didn't just change the ranking. It changed which brands were in the answer at all.
If you only run the generic prompt, you’d never know Attio has a page that wins when the buyer is specified. This is why you should run your highest-value prompts twice when establishing your baseline.
Turn findings into a ranked fix list
You’ve run all four layers, you’ve seen real examples of the different failure states. You should have a good idea of how healthy your prompts are and your overall AI visibility score.
A GEO audit report that ends here, with a list of findings at different layers, is incomplete. Turn your knowledge into a ranked “fix list.” Sequence by layer first, always, then by effort within a layer. Use a GEO audit checklist to ensure you’re solving all your diagnoses issues.
A crawler block outranks a schema gap regardless of how long each takes. A missing extractable answer outranks a passage rewrite. You fix the cheapest layer that’s failing before you touch the expensive one above it. This isn’t because it’s more important, but because nothing above it works until it’s clear.
The part no one-off GEO audit can cover
Unfortunately, you can’t run a one-off audit, address your findings, and never touch it again. An audit is a snapshot, and AI visibility is constantly moving.
Based on Omnia’s citation data, only 19.8% of Gemini prompts kept the same top-cited source across a four-week window. That means roughly 4 in 5 changed their lead source at least once a month, and nearly half swapped it three times or more. Every engine has its own retrieval methods, so while this is Gemini-specific you can expect instability across every AI model.
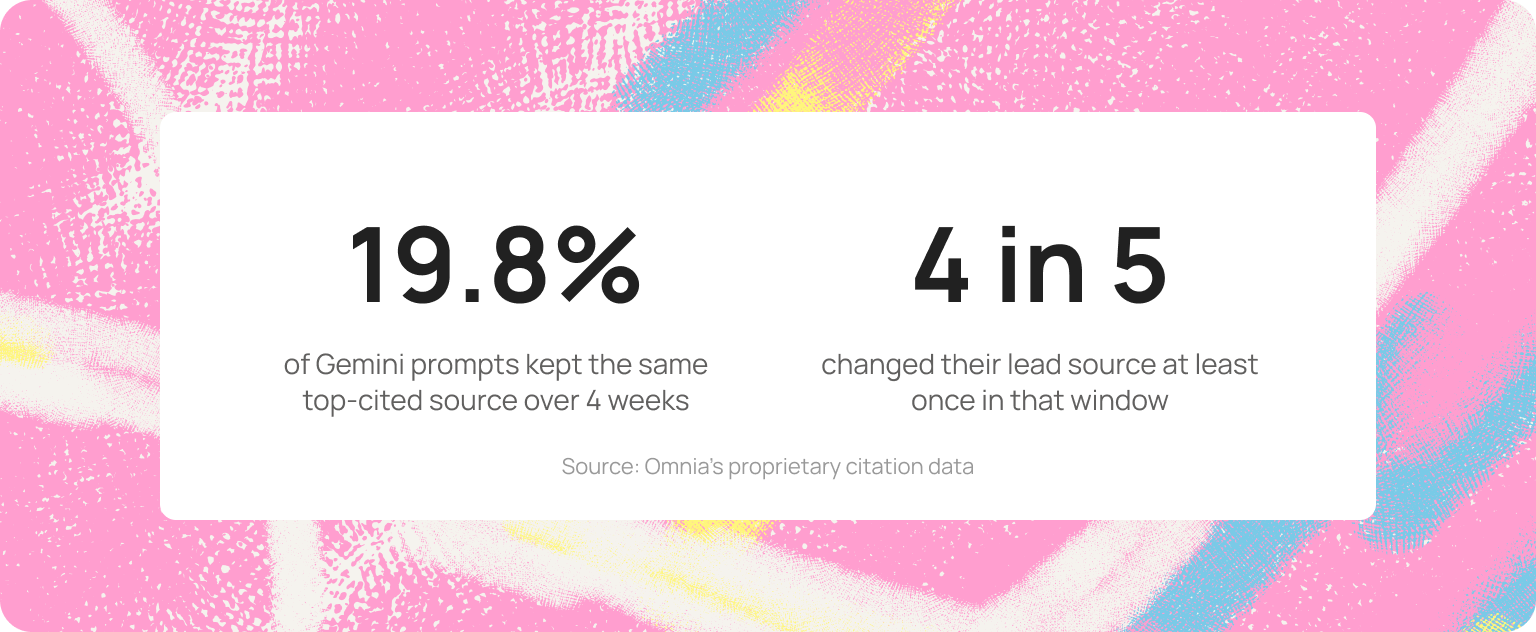
This AI visibility volatility means you need to re-run your baseline layer on a fixed cadence. We recommend monthly for a full audit and weekly for your prompt set.
Already feeling overwhelmed? A manual GEO audit is a lot of work and stops scaling at roughly 20-30 prompts across three engines. This doesn’t even take into account how AI visibility varies across countries and regions. That’s why many teams invest in an AI search monitoring tool.
Where Omnia and Omnio fit
Omnia is an AI platform that tells you where and how your brand appears in the top AI engines, then tells you how to act on that data. Omnio, Omnia’s GEO agent, integrates with your existing toolstack to tackle all the GEO tasks you don’t have time for, like generating a query fan out or reporting on your AI visibility data to leadership.
Or, running a GEO site audit exactly like the one we’ve been talking about.
- Omnio runs the audit: It crawls your site to identify gaps in technical accessibility and GEO, and hands you an actionable report ranked by impact. For large sites, it audits representative pages per template instead of crawling everything blindly, so you get signal without the wait.
- Omnio drafts the fixes: It turns the top gaps into the specific pages to create and the existing pages to fix. It performs page rewrites based on the exact passage a competitor is cited for, creates new content for prompts where you’re absent, then re-measures against the baseline. Every public action is approval-gated. Nothing goes live until you approve it.
- Omnia runs the baseline continuously: Tracked prompts, answers, and citations at scale, across engines, so the baseline is a trend rather than a snapshot. This is the part that manual auditing can't sustain past 20–30 prompts across three engines.
- Omnia gives you Layer 3 without the manual logging: Cited domains surfaced and sorted, which is the single most tedious part of the manual process. You can see the source pool without hand-logging every citation.
- It remembers the audit, so the next one is not from scratch: Persistence across sessions, context carried forward.
- Two ways in, depending on who is driving: Omnia’s MCP server puts the data inside the assistant you already use (like Claude or ChatGPT). Omnio does the work inside Omnia grounded in that same data. Two entry points, same data layer.
The audit tells you why you're invisible. The question is whether you re-run it by hand every month or whether something runs it for you. Book a demo or start Omnia for free for 14 days.
FAQs
How long does a GEO audit take?
The baseline takes a full day for 20-30 prompts across three engines. Layer 1 is minutes per page as you're checking robots.txt and running a curl command. Layer 2 takes longer since you’re checking passage structure on each page. Layer 3 is the most time-consuming since you're logging every cited domain by hand. The real time investment isn’t running the audit, it’s implementing the fixes you find.
How do I improve content structure to boost my current AI visibility?
Pushing too hard to optimize for AI can make your content worse for actual readers, which defeats the purpose. Without structured data, AI systems struggle to parse what’s on your page. Break content into short sections under clear, question-shaped headings as this gives generative search engines discrete passages they can lift. Long, dense blocks of text are rarely quoted because the engine can’t extract a clean sentence from them.
Do I need a paid AI tool to run a GEO audit?
You can run a free GEO audit using the steps in this guide. All you need is a browser, a spreadsheet, and time. For a quick baseline check, Omnia offers a free AI visibility checker that shows your brand’s presence across generative AI engines. If you want the full audit run for you including crawling, gap identification, and drafted fixes, a dedicated AI tool like Omnia offers a 14-day free trial.
What is the difference between an SEO and a GEO audit?
A traditional SEO audit checks whether your site is crawlable and whether you rank for target keyword rankings. Search engine optimization focuses on the ten blue links on a search results page. A GEO audit, part of generative engine optimization, goes further. It checks whether AI-generated answers can actually extract and cite your content. Passing an SEO audit doesn’t mean you’ll appear in AI answers, which is why the two complement each other rather than replace each other.
Which AI engines should I audit against?
The two or three your buyers actually use. For most B2B SaaS companies, that’s ChatGPT and Perplexity. For consumer-facing brands, Google AI Mode and Gemini matter more. Don't try to track all six or you’ll get a shallow picture everywhere. The citation budget varies so widely across engines (ChatGPT averages 4.1 citations per answer, AI Mode 13.8) that “absent” means something different on each one.